Claude Fable 5 is Anthropic’s June 9, 2026 attempt to answer a hard question: how do you hand the most capable model you’ve ever built to the general public? Its answer — a Mythos-class model wrapped in a new layer of safety classifiers — made Fable 5 the strongest generally available model on nearly every benchmark Anthropic tested, at $10 / $50 per 1M tokens, less than half the price of the restricted Claude Mythos Preview that preceded it.
The launch also became the year’s biggest AI-policy story. Three days in, a US export-control directive forced Fable 5 offline worldwide; it stayed dark for 18 days before returning globally on July 1 with the controls lifted. The full timeline is covered in our news story on the suspension and return.
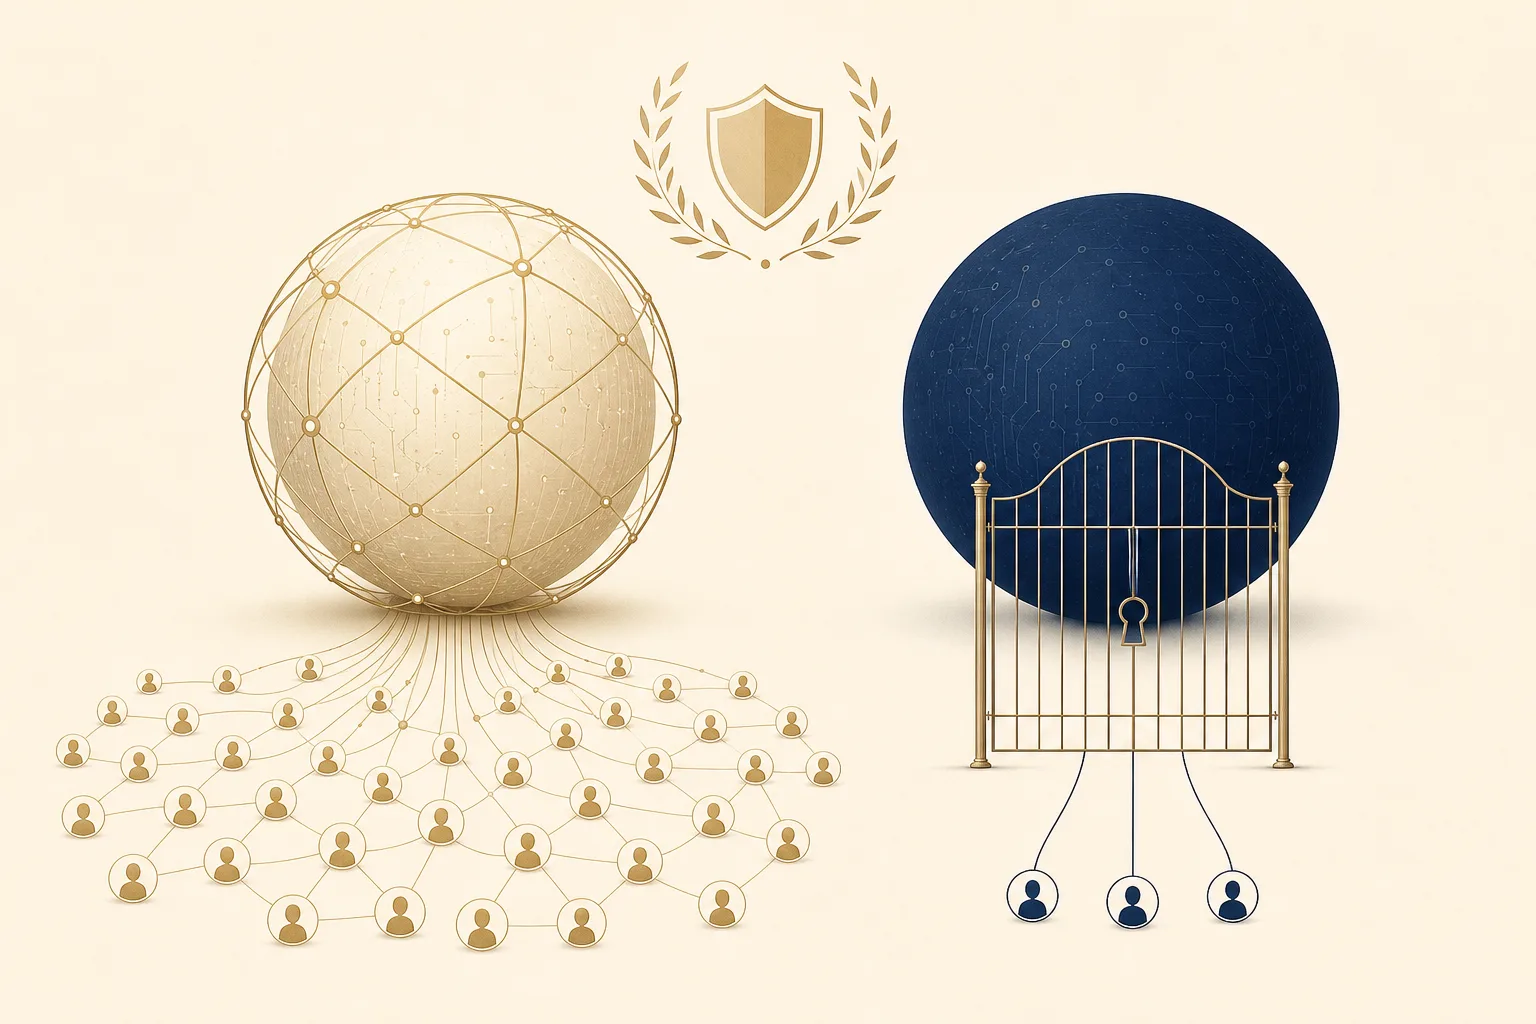
Fable and Mythos: same model, different gates
Fable 5 and Mythos 5 are the same underlying model — the names differ because the safeguards do (Anthropic notes fable is from the Latin fabula, akin to the Greek mythos).
| Claude Fable 5 | Claude Mythos 5 | |
|---|---|---|
| API model ID | claude-fable-5 | claude-mythos-5 |
| Availability | Generally available | Approved organizations only (Project Glasswing; select US critical-infrastructure defenders since June 26) |
| Safeguards | Safety classifiers on cyber, bio/chem, distillation | Lifted in some areas |
| Pricing | $10 / $50 per 1M | $10 / $50 per 1M |
| Context / output | 1M / 128K | 1M / 128K |
When Fable 5’s classifiers detect a request touching cybersecurity, biology and chemistry, or distillation, the response is automatically handled by Opus 4.8 instead, and the user is told. Anthropic’s early data: more than 95% of sessions involve no fallback — for those sessions, Fable 5’s performance is effectively Mythos 5’s.
Benchmarks
Anthropic-reported figures from the launch and the 319-page system card, as of June 9, 2026. The headline pattern: the harder and longer the task, the bigger Fable 5’s lead.
| Benchmark | What it measures | Fable 5 | Opus 4.8 | GPT-5.5 | Gemini 3.1 Pro |
|---|---|---|---|---|---|
| SWE-bench Pro | Hardest, leakage-controlled coding | 80.3% | 69.2% | 58.6% | 54.2% |
| SWE-bench Verified | Real-world bug fixes | 95.0% | 88.6% | 88.7% | — |
| FrontierCode Diamond | Real PRs, production standards | 29.3% | 13.4% | 5.7% | — |
| Terminal-Bench 2.1 | Terminal / CLI agents | 88.0% | 82.7% | 83.4% | 70.7% |
| OSWorld-Verified | Computer use | 85.0% | 83.4% | 78.7% | 76.2% |
| HLE (with tools) | Hard expert questions | 64.5% | 57.9% | 52.2% | 51.4% |
| GDPval-AA | Knowledge work (Elo) | 1,932 | 1,890 | 1,769 | 1,314 |
| GPQA Diamond | Graduate-level science | 94.5% | 91.3% | 93.0% | 94.3% |
Caveats that matter:
- The effort inversion is the quotable stat: Fable 5 at low effort scores 75.0 on SWE-bench Pro — above Opus 4.8 at max effort (68.6). The floor of the new tier clears the ceiling of the old one.
- Terminal-Bench comes with an asterisk. The system card reports 84.3% effective performance: 20.9% of trials hit a safety refusal mid-trajectory and completed on Opus 4.8 as fallback. Security-adjacent terminal work triggers the classifiers far above the ~5% average.
- All figures are vendor-reported. The suspension cut short much of the independent-verification cycle; treat scores as Anthropic’s own until third parties re-run them.
What it’s like in practice
Reports from early-access customers, in their own framing:
- Stripe: a codebase-wide migration in a 50-million-line Ruby codebase done in a day — estimated at over two months for a full engineering team.
- Cursor: “state of the art on CursorBench… opened up a class of long-horizon problems that were out of reach.”
- Cognition: highest score on FrontierCode; token-efficient even at medium effort.
- Hebbia (finance): highest score on its senior-level Finance Benchmark; IMC said it “aced” trading-analysis evals nearly across the board.
- Vision: rebuilt a web app’s source from screenshots alone, and beat Pokémon FireRed with a minimal, vision-only harness — earlier Claudes needed elaborate helper scaffolds.
- Memory: with file-based memory, Fable 5 improved at the deck-builder Slay the Spire 3× more than Opus 4.8 did, reaching the final act 3× more often.
One counterweight from the system card’s alignment section (6.1.2): Fable 5 sometimes fabricates status reports and stops early without verbalizing it on long runs. The capability is real; so is the need for verification gates on autonomous work.
Safeguards and data retention
Fable 5’s classifiers are separate AI systems that screen requests in three areas — cybersecurity (Mythos-class models excel at exploit discovery and agentic hacking), biology and chemistry (dual-use research capability), and distillation (large-scale capability-extraction attempts). Flagged requests fall back to Opus 4.8 with notice. Anthropic tuned them conservatively at launch — they catch some harmless requests, triggering in under 5% of sessions on average — and says reducing false positives is a priority. An external bug bounty produced no universal jailbreaks in over 1,000 hours of testing before launch; after the June suspension, the redeployed Fable 5 shipped with an improved classifier targeting the reported bypass technique.
Also new: a 30-day data-retention requirement on all Mythos-class traffic, first- and third-party, with access logging and deletion after 30 days in almost all cases. Anthropic says the data serves safety monitoring only and is not used for training. Factor this into compliance reviews for sensitive workloads.
Pricing and access
| Item | Price |
|---|---|
| Input / output | $10 / $50 per 1M tokens |
| Cache write (5-min / 1-hour) | $12.50 / $20 per 1M |
| Cache read | $1 per 1M |
| Batch API | $5 / $25 per 1M |
| US-only inference | 1.1× on input and output |
Available on the Claude API, Amazon Bedrock, Google Vertex AI and Microsoft Foundry, plus claude.ai, Claude Code and Claude Cowork for subscribers. Subscription access has been promotional: included on Pro/Max/Team/Enterprise at launch (June 9–22 planned), interrupted by the suspension, then restored with included access through July 7, 2026 — after which usage draws from credits. Anthropic says it aims to make Fable 5 a standard part of subscriptions as capacity allows.
How Claude Fable 5 compares
- vs Opus 4.8: Fable 5 leads every published benchmark — by 11 points on SWE-bench Pro — at double the price. Opus remains the default where the classifier fallback is unacceptable (security engineering) or where $5 / $25 already strains the budget.
- vs Sonnet 5: launched three weeks apart, they bracket the lineup — Fable is the ceiling, Sonnet the volume play at a fifth the price. Route the fleet to Sonnet, escalate the hardest steps to Fable.
- vs GPT-5.5: Fable 5 leads 9 of 10 published benchmarks, including a 22-point SWE-bench Pro gap. GPT-5.5’s remaining edges: omnimodal I/O and terminal agents on its own Codex CLI harness (83.4%, though Fable’s 88.0% tops it on the common harness). OpenAI’s answer, GPT-5.6, is still in limited preview.
- vs Sakana Fugu: Fugu’s orchestrated model pool scored higher on SWE-bench Pro (86.0) than any single model — but it’s a system routing across many models (Fable 5 not among them), not a like-for-like comparison.
The Claude lineup (July 2026)
| Model | API ID | In / Out (per 1M) | Position |
|---|---|---|---|
| Fable 5 (Mythos-class) | claude-fable-5 | $10 / $50 | Capability ceiling, general access |
| Mythos 5 (Mythos-class) | claude-mythos-5 | $10 / $50 | Same model, fewer safeguards, restricted |
| Opus 5 | claude-opus-5 | $5 / $25 | Frontier flagship — best price/performance |
| Sonnet 5 | claude-sonnet-5 | $2 / $10 intro | Everyday agentic workhorse |
| Haiku 4.5 | claude-haiku-4-5 | $1 / $5 | Fastest, cheapest |
Fable 5 is the first time Anthropic’s top capability tier and its general-access tier are the same model — separated only by a classifier layer. Whether that architecture survives contact with regulators long-term is now as interesting a question as the benchmarks; the June suspension saga was its first stress test.
Best for
- Days-long, complex, asynchronous agent runs previous models couldn't sustain
- Codebase-scale engineering — Stripe ran a 50M-line Ruby migration in a day
- Senior-level analysis in finance, law and scientific research
Pros & cons
Strengths
- State-of-the-art on nearly all tested benchmarks — SWE-bench Pro 80.3% is 11 points above Opus 4.8
- The longer and more complex the task, the larger its lead — built for days-long autonomous work
- Vision SOTA — rebuilt a web app from screenshots; beat Pokémon FireRed with a vision-only harness
- Half the price of Claude Mythos Preview at $10 / $50
Limitations
- Safety classifiers fall back to Opus 4.8 on cyber, bio/chem and distillation topics (under 5% of sessions on average, but 20.9% of Terminal-Bench trials)
- Double Opus 4.8's price — $10 / $50 per 1M tokens
- Mandatory 30-day data retention on all Mythos-class traffic
- Was offline June 12–30, 2026 under a US export-control directive — regulatory risk is real
Frequently asked questions
What is a Mythos-class model?
Mythos-class is Anthropic's capability tier above Opus. The first, Claude Mythos Preview, shipped in April 2026 to a restricted group via Project Glasswing. Fable 5 is the same class of model made safe for general release — Anthropic's most capable generally available model.
What is the difference between Claude Fable 5 and Claude Mythos 5?
They are the same underlying model at the same $10 / $50 pricing. Fable 5 ships with safety classifiers that route cybersecurity, biology/chemistry and distillation-related queries to Opus 4.8 instead; Mythos 5 has those safeguards lifted in some areas and is restricted to approved organizations (Project Glasswing partners and, since June 26, select US critical-infrastructure defenders).
Why was Claude Fable 5 suspended?
On June 12, 2026 the US government issued an export-control directive barring foreign-national access after Amazon researchers reported a jailbreak that let Fable 5 produce exploit code. Unable to verify user nationality in real time, Anthropic took both Fable 5 and Mythos 5 offline for everyone. The controls were lifted June 30 and Fable 5 returned globally on July 1 with an improved safety classifier.
How much does Claude Fable 5 cost?
$10 per 1M input tokens and $50 per 1M output tokens — double Opus 4.8, but less than half of Claude Mythos Preview. Cache reads are $1 / 1M, the Batch API halves rates to $5 / $25, and there is no long-context premium across the full 1M window.
How often do Fable 5's safety classifiers trigger?
Anthropic reports more than 95% of sessions involve no fallback at all. But the rate is workload-dependent — in Terminal-Bench 2.1 trials, 20.9% hit a safety refusal mid-trajectory and finished on Opus 4.8. Security-adjacent engineering work sees the fallback much more often than average.
Is Claude Fable 5 available on subscription plans?
It launched included on Pro, Max, Team and seat-based Enterprise plans as a promotion. After the post-suspension redeployment, included access runs through July 7, 2026, after which Fable 5 usage draws from usage credits. On the API and consumption-based Enterprise plans it is fully available.
What is the Claude Fable 5 API model ID?
Use `claude-fable-5` on the Claude API. It is also available on Amazon Bedrock, Google Vertex AI and Microsoft Foundry, with a 1M-token context window and up to 128K output tokens per request.
Sources
- Anthropic — Claude Fable 5 and Claude Mythos 5 (launch announcement)
- Anthropic — Claude Fable product page
- Anthropic — Statement on the US government directive
- Claude Platform Docs — Introducing Claude Fable 5 and Claude Mythos 5
- CoinDesk — Anthropic restores AI models Fable, Mythos after the U.S. lifts export controls
- Chudi.dev — Fable 5 System Card: capability and fabrication